The distinction between open and closed software is no longer a simple binary but a nuanced spectrum involving web servers, open-weight models, and subscription-based corporate platforms. This realization follows a period of rapid acceleration in which the survival of pharmaceutical tools depends on their adaptability to complex biological data. As the industry integrates machine learning into every facet of the drug development life cycle, the tension between community-driven transparency and proprietary protection has reached a tipping point. This environment forces researchers to weigh the immediate costs and benefits of open-source libraries against the long-term reliability and regulatory peace of mind offered by high-cost, closed-loop ecosystems. Ultimately, the choice between these pathways dictates the speed at which a candidate molecule moves from a digital concept to a clinical therapy, reshaping the competitive landscape for academic institutions and global pharmaceutical giants alike. The current era necessitates a move away from rigid categorization toward a strategic understanding of software accessibility and its impact on innovation.
Navigating the Spectrum of Accessibility
The Transition: From Proprietary Dominance to Open-Source Utility
The paradigm of pharmaceutical research has shifted significantly from a reliance on expensive, local software licenses to a more democratic landscape where open-source tools handle the bulk of routine scientific labor. For standard bench research and educational applications, the modern pharmaceutical scientist no longer requires the exorbitant proprietary licenses that once served as gatekeepers to high-level analysis. Robust communities now support tools for basic tasks such as chemical structure depiction, calibration curve fitting, and fundamental pharmacokinetic analysis. This shift has not only lowered the entry barrier for smaller research laboratories but has also fostered a culture of collaborative validation that was previously impossible within the “black box” environment of commercial software. Consequently, the reliance on traditional vendors for basic computational needs has eroded, allowing research budgets to be redirected toward more specialized, high-impact data generation projects that drive the industry forward.
Furthermore, the emergence of the “open-weight” middle ground has provided a hybrid solution that balances technical depth with accessibility. These models allow researchers to examine the underlying architecture and weights while keeping the original training data proprietary, offering a compromise between total transparency and corporate secrecy. This middle path has become especially popular for organizations that want to leverage the collective intelligence of the open-source community without fully exposing their proprietary datasets to competitors. By adopting these flexible models, laboratories can customize their computational pipelines to a degree that was previously restricted by the rigid terms of service associated with closed commercial suites. This flexibility has proven essential for the rapid prototyping of new drug candidates, where the ability to tweak an algorithm’s internal logic can lead to breakthroughs that standardized commercial tools might overlook due to their fixed configurations.
Data Sovereignty: Security and Intellectual Property Barriers
Despite the growing utility of open-source tools, the pharmaceutical industry continues to grapple with the inherent security risks associated with free web-based services. A primary concern for researchers is that many free servers require the uploading of sensitive molecular or biological data to remote, third-party infrastructure. For an end-to-end drug discovery campaign where intellectual property is the most valuable asset, the risk of data leakage or unauthorized access on a public server is often deemed unacceptable. This reality ensures a persistent market for proprietary, on-premises closed-loop systems that guarantee data isolation and rigorous cybersecurity protocols. When the potential value of a patent reaches billions of dollars, the cost of a subscription-based corporate platform becomes a necessary insurance policy against the catastrophic loss of proprietary information.
Moreover, the requirements for regulatory filings frequently necessitate the use of software with validated lineages and contractual vendor support. Health authorities often demand a high degree of accountability that can only be provided by established software companies capable of offering comprehensive documentation and technical audits. For workflows intended for submission to agencies like the FDA, the “Software of Unknown Provenance” classification associated with many community-maintained repositories can pose a significant administrative hurdle. Proprietary suites provide a sense of stability and a clear chain of custody for the data processing methods used, which is critical during the review process. This divide creates a bifurcated environment where open-source tools dominate the early, exploratory phases of research, while closed commercial ecosystems remain the standard for the late-stage development and regulatory phases of the pharmaceutical lifecycle.
Strategic Selection in Early Discovery and Chemistry
Breakthroughs: Protein Structure and Modeling
The discovery phase is currently witnessing a rapid divergence between community-driven repositories and vendor-managed systems, specifically within the high-stakes field of protein structure prediction. While elite commercial entities use proprietary engines to gain a competitive edge, academic and independent researchers have successfully deployed open-weight frameworks such as OpenFold, Chai-1, and Protenix to conduct world-class research. These tools have democratized the ability to predict how proteins fold and interact with other molecules—a task that was once computationally prohibitive for all but the most well-funded institutions. The accessibility of these frameworks has sparked a wave of innovation in structural biology, leading to the identification of novel drug targets that were previously considered “undruggable” due to the lack of clear structural data.
A significant advancement in this area is the introduction of frameworks such as Boltz-2, which aim to predict both macromolecular structures and the binding affinity of small molecules simultaneously. This tool represents a leap forward by attempting to achieve performance levels comparable to traditional physics-based free-energy perturbation calculations at a fraction of the computational cost. Early reports suggest that these AI-driven models can reduce the cost of such calculations by a factor of one thousand, potentially saving millions of dollars in computational resources during the screening process. However, the scientific community maintains a cautious stance toward these developments, as many claims are currently found in unreviewed preprints rather than peer-reviewed journals. Rigorous independent replication remains a requirement before these models can be fully integrated into the industry’s standard operating procedures, highlighting the ongoing tension between technological speed and scientific rigor.
The Practical Realities and Challenges of Integrating Generative Chemistry with Molecular Docking for Advanced Drug Discovery Applications
In the realm of generative chemistry, the ecosystem has expanded to allow for the design of potent inhibitors in remarkably short time frames. Open architectures now allow academic institutions to execute complex de novo design pipelines that were once the exclusive domain of large pharmaceutical companies. By utilizing toolkits like RDKit and DeepChem, which are supported by massive open databases like PubChem and ChEMBL, researchers can generate molecular descriptors and design novel compounds without the burden of licensing fees. This has accelerated the early-stage pipeline, with some projects demonstrating the ability to design functional inhibitors for specific kinases in as little as three weeks. This speed is essential for responding to emerging health threats or exploring niche therapeutic areas that might not attract immediate commercial interest.
However, when it comes to molecular docking—the process of predicting how a small molecule binds to a protein target—the latest AI models have encountered significant challenges. Independent benchmarking from evaluation suites like PoseBusters suggests that deep learning docking engines do not consistently outperform classical, physics-based software like AutoDock Vina. These advanced models often struggle with physical plausibility and geometric generalization when they encounter molecular complexes that were not well-represented in their initial training data. This serves as a critical reminder that “new” is not always synonymous with “better” in a scientific context. The reliability of traditional software, which relies on well-understood physical laws rather than pattern recognition, remains a cornerstone of the discovery process. This reinforces the need for a balanced approach that combines the generative power of AI with the structural accuracy of established physics-based methods.
Physical Implementation and Clinical Integration
Automated Laboratories: From Digital to Physical
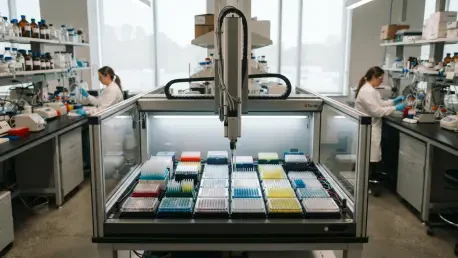
The application of artificial intelligence has successfully transitioned from purely digital environments into physical wet labs through the rise of automated synthesis and formulation design. A recent landmark development involved the use of an autonomous frontier language model, GPT-5.4, coupled with high-throughput robotics to optimize complex chemical reactions. In one instance, the AI was tasked with optimizing the Chan-Lam coupling reaction for primary sulfonamides, a process notoriously difficult to refine. Through a massive screening campaign involving over 10,000 reactions, the system identified TEMPO as a mild additive that significantly boosted product yields. This achievement demonstrated how AI can serve as more than just a data analyzer; it is now a physical laboratory assistant that can enhance chemical yield and experimental efficiency at a scale impossible for human researchers alone.
In addition to synthesis, AI is making significant strides in the field of formulation and absorption, with web-based platforms now being used to forecast excipient compatibility and predict how various drug formulations will behave once they enter the human body. These physiologically based pharmacokinetic platforms allow researchers to predict human disposition profiles across hundreds of datasets, effectively bridging the gap between virtual chemical design and physical clinical application. By simulating how a drug moves through the digestive system and enters the bloodstream, scientists can optimize formulations long before the first human trial begins. This predictive capability reduces the risk of late-stage failures due to poor bioavailability or unexpected metabolic issues, making the development process both more cost-effective and safer for trial participants.
Clinical Advancement: Digital Twins and Simulation
In the middle stages of development, AI is increasingly used as a supplement to empirical assays and animal experiments rather than a total replacement. While commercial suites remain the industry standard due to their extensive validation, open-source alternatives like the Open Systems Pharmacology suite have emerged as powerful competitors. For example, metabolic studies have shown that open-source tools can achieve predictive accuracy comparable to the most expensive industry software. These tools are often supported by automated qualification frameworks that ensure high precision in metabolic interaction predictions. This level of accuracy is vital for designing safe dosing regimens and understanding how a new drug might interact with other medications a patient is already taking, a critical factor in the success of any clinical program.
The clinical trial phase is also being revolutionized by the development of “digital twins,” which are machine-learning models built using historical patient data. These models forecast the trajectories of control arms in trials, allowing researchers to improve the statistical power of their studies while potentially reducing the number of human participants required for a control group. This approach has already begun to receive qualification from regulatory bodies like the European Medicines Agency, signaling a major shift in how clinical evidence is gathered and analyzed. By using prognostic adjustments derived from these digital twins, pharmaceutical companies can run more efficient trials that reach conclusions faster without compromising patient safety or data integrity. This integration of historical data and predictive modeling represents a new frontier in the clinical validation of medicine.
Governance: Risk and the Human Element
Regulatory Frameworks: Ensuring Model Credibility
As AI becomes more deeply integrated into pharmaceutical submissions, health authorities have established formal governance frameworks to manage the associated risks. The U.S. Food and Drug Administration has issued guidance proposing a seven-step risk-based credibility framework that focuses on the “context of use” for every algorithm. This approach acknowledges that the level of scrutiny an algorithm requires should be proportional to its potential impact on patient safety. If an algorithm is used for a low-risk task like data organization, it requires less oversight than one used to predict drug toxicity or clinical trial outcomes. This nuanced regulatory approach ensures that innovation is not stifled by excessive red tape while maintaining high standards for the models that directly affect human health.
Furthermore, the European Medicines Agency has adopted principles of good practice that treat unverified third-party machine learning code as “Software of Unknown Provenance.” This classification requires pharmaceutical companies to maintain rigorous inventory control and active monitoring of any AI tools they use in their development pipelines. To establish credibility, models must be evaluated across five verifiable dimensions: predictive performance, reproducibility, data provenance, regulatory alignment, and the quality of human oversight. These standards ensure that the “black box” nature of some AI models is mitigated through transparent documentation and verifiable testing. By adhering to these frameworks, the industry can ensure that the AI tools it relies on are as reliable and auditable as any traditional laboratory instrument, protecting the integrity of the drug development process.
The Human Factor: Oversight and Literacy
A key component of the current evolution in pharmaceutical AI is the necessity of “structured” human involvement, which is categorized by the degree of intervention required. Researchers must distinguish between being “in-the-loop,” where they actively validate every step, and being “on-the-loop,” where they supervise autonomous processes. The highest level of responsibility remains being “in-command,” which involves holding the ultimate institutional authority over the AI’s outputs and ethical implications. A significant concern for the industry is “automation bias,” a phenomenon where human researchers might passively accept algorithmic results without sufficient skepticism. To prevent this, institutions must prioritize the training of scientists who can critically evaluate AI outputs rather than simply operating the software.
The long-term success of pharmaceutical research will depend on a deep foundational literacy in model validation and algorithmic governance rather than the mastery of any specific software package. As “self-driving” laboratories handle more of the design-make-test-analyze cycles, the value of human scientists will shift toward causal interpretation, experimental confirmation, and ethical accountability. The ultimate competitive advantage in 2050 will be the ability to manage the provenance of software while maintaining uncompromising scientific scrutiny. This ensures that even as the technical ability to run simulations becomes ubiquitous, the ability to derive meaningful, safe, and effective medical insights remains a uniquely human endeavor. The tools that survive this process will be those that empower human experts to make better decisions faster, rather than those that attempt to replace them entirely.
Future Considerations for Scientific Rigor
The review of current computational trends concluded that the survival of AI tools in the pharmaceutical sector depended more on their transparency and auditability than on their raw processing speed. Researchers recognized that while closed-loop corporate platforms offered a safety net for intellectual property and regulatory compliance, the burgeoning open-source ecosystem provided the flexibility and collaborative potential necessary for rapid early-stage discovery. The industry learned that the most effective strategy involved a hybrid approach, utilizing open tools for exploratory work while transitioning to validated, proprietary systems for the final stages of clinical development and regulatory submission. This balance allowed for a more efficient allocation of resources and a faster path to market for innovative therapies.
Looking forward, the industry must prioritize the development of standardized benchmarks and qualification frameworks to ensure that AI-driven discoveries remain robust and reproducible. The shift toward “self-driving” laboratories and digital twins suggests a future where the physical and digital realms are indistinguishable, yet the core of the scientific process—experimental confirmation and ethical oversight—must remain the responsibility of human experts. Actionable next steps for pharmaceutical organizations include investing in foundational data literacy for their workforce and establishing clear protocols for the use of “Software of Unknown Provenance.” By fostering a culture of algorithmic skepticism and rigorous validation, the pharmaceutical community can ensure that the evolution of AI continues to serve the ultimate goal of improving patient outcomes through safer and more effective medicine.